AI APIs for Developers
Filter by use case
AI Model APIs
217 models
ModelsLab
Qwen 2.1 Image to Image
Transform existing images with Qwen 2.1 Image-to-Image. Upload an image and describe your desired changes in a natural-language prompt to generate an updated result.
ModelsLab
Qwen Image 2.1 Text to Image
Generate high-quality images from natural-language prompts with Qwen Image 2.1. Describe the scene, subject, style, composition, lighting, or visual details you want, and the model turns your instructions into a detailed image.
ModelsLab
Minimax H3 Fast Reference To Video
Minimax H3 Fast is an open-weight multimodal AI video model that creates up to 15-second videos with native stereo audio. Generate and transform videos using text, images, video, or audio with support for image-to-video, video-to-video.
Open Ai
GPT-Image-2.5 Flare - Image Edit
GPT Image 2.5 transforms how images get edited. Upload any photo — a product shot, portrait, marketing asset, or personal image — and simply describe what you want changed. Swap the background, adjust lighting, remove objects, add readable text.
Open Ai
GPT-Image-2.5 Flare - Text To Image
GPT Image 2.5 is OpenAI's most advanced text-to-image model. Describe any scene, concept, poster, product visual, or creative idea in plain language — and the model thinks through your brief, plans the layout.
Open Ai
GPT-Image-2.5 Sunburst - Image Edit
GPT Image 2.5 transforms how images get edited. Upload any photo — a product shot, portrait, marketing asset, or personal image — and simply describe what you want changed. Swap the background, adjust lighting, remove objects, add readable text.
Open Ai
GPT-Image-2.5 Sunburst - Text To Image
GPT Image 2.5 is OpenAI's most advanced text-to-image model. Describe any scene, concept, poster, product visual, or creative idea in plain language — and the model thinks through your brief, plans the layout.
Alibaba
Wan 3.0 Reference To Video
Feed Wan 3.0 one or more reference images and generate video that keeps faces, characters, and objects consistent shot after shot — ideal for branded content, avatars, and multi-scene storytelling via the ModelsLab API.
Alibaba
Wan 3.0 Image To Video
Bring any photo to life with Wan 3.0's image-to-video model. Upload a source image, describe the motion, and get a smooth, physically consistent AI video — built for product, portrait, and creative animation via the ModelsLab API.
Alibaba
Wan 3.0 Text To Video
Turn any text prompt into a cinematic AI video with Wan 3.0 — Alibaba's next-gen video model. Sharper motion, longer clips, and stronger prompt adherence than Wan 2.5, available now via the ModelsLab API.
ModelsLab
MiniMax H3 Start/ End Frame
MiniMax H3 is an open-weight multimodal AI video generation model capable of creating up to 15-second videos with native stereo audio from text, images, video, and audio inputs. It supports text-to-video, image-to-video, video editing, and video-to-video
ModelsLab
Minimax H3 Reference to Video
MiniMax H3 is an open-weight multimodal AI video generation model capable of creating up to 15-second videos with native stereo audio from text, images, video, and audio inputs. It supports text-to-video, image-to-video, video editing, and video-to-video
ltx
LTX 2.5 Pro Text To Video
LTX 2.5 Pro turns text prompts into cinematic video with native synchronized audio — dialogue, ambience, and sound effects generated alongside the frames. Output at 720p or 1080p, 25 or 50 fps, up to 10 seconds, from a single ModelsLab API call.
ltx
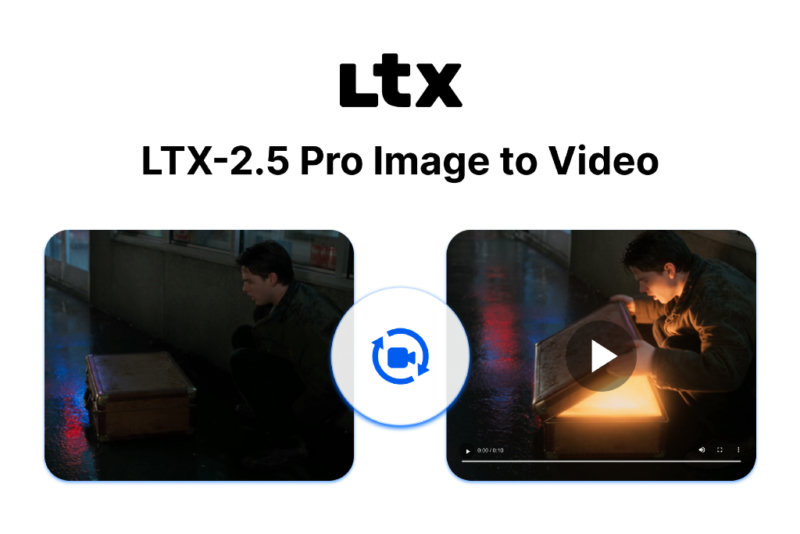
LTX 2.5 Pro Image To Video
LTX 2.5 Pro Image to Video animates a single still into a cinematic clip, using a text prompt to direct motion, camera movement, and atmosphere. Native synchronized audio, 720p or 1080p output, 25 or 50 fps, and 6 to 10 second durations — all from one end

ModelsLab
Minimax H3 Text to Video
MiniMax H3 is an open-weight multimodal AI video generation model capable of creating up to 15-second videos with native stereo audio from text, images, video, and audio inputs. It supports text-to-video, image-to-video, video editing, and video-to-video
xAI
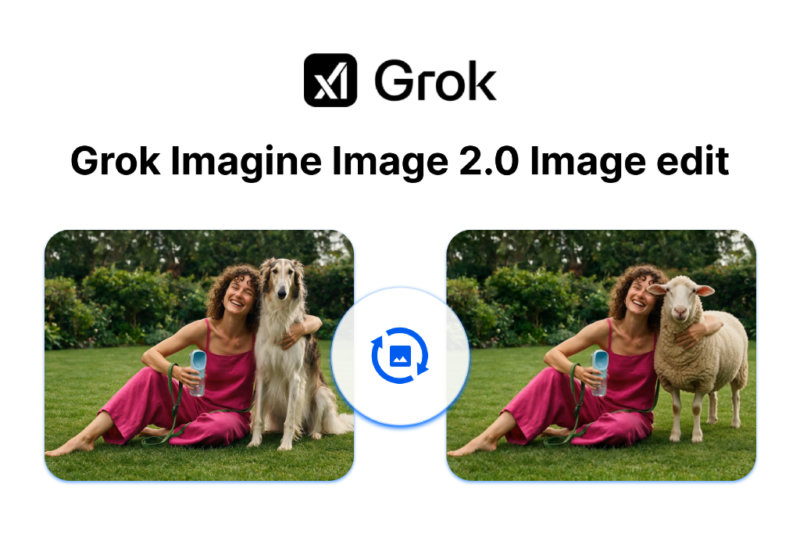
Grok Imagine Image 2.0 Image Edit
Grok Imagine Image 2.0 Image Editing modifies existing images from plain text instructions — add, remove, restyle, or merge subjects while preserving the original look. Handles up to 14 input images in a single generation across seven aspect ratios.